Thinkputer AI: Slow Response -> Fast Local AI
Submitted by on Thu, 08/27/2026 - 20:44Thinkputer AI: Slow Response → Fast Local AI
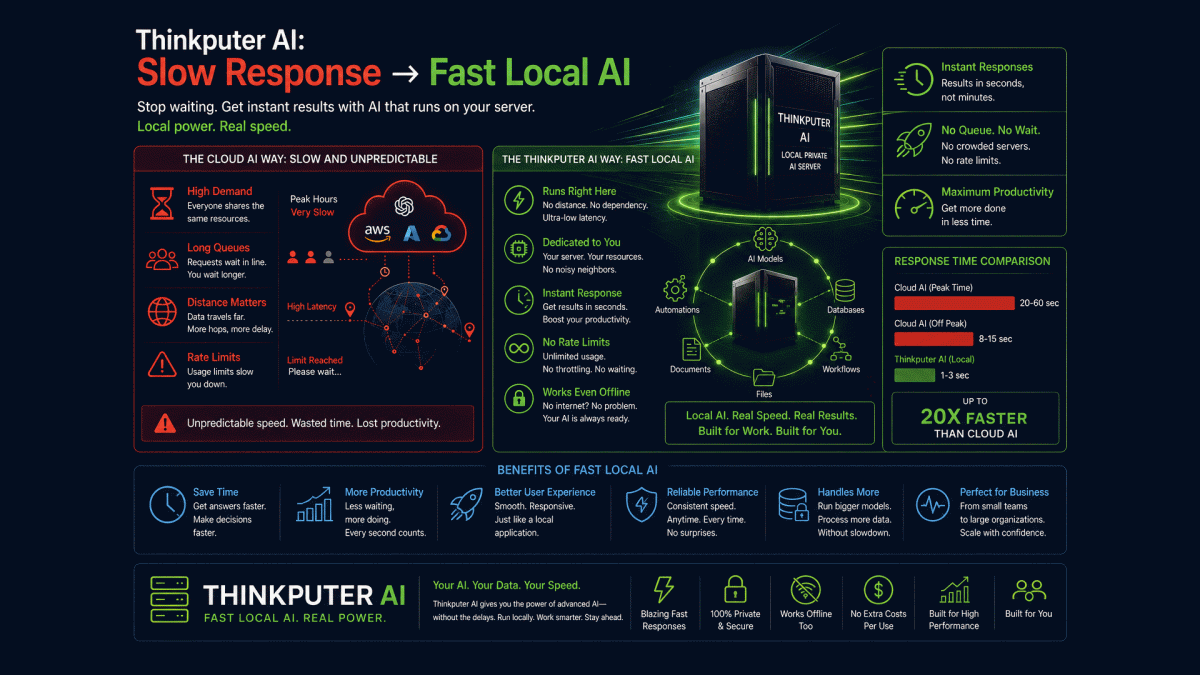
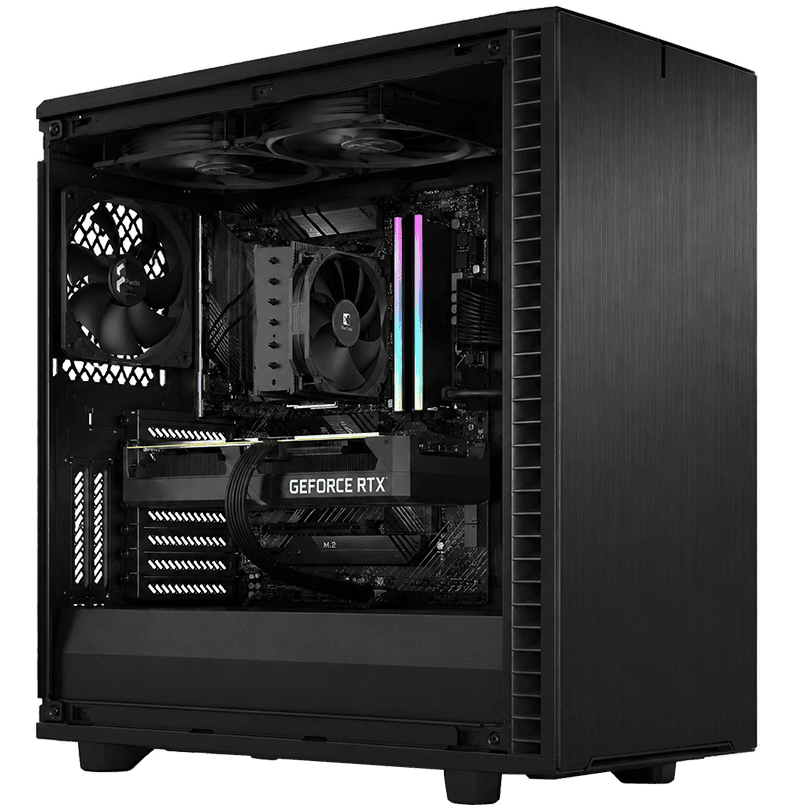
Cloud AI requests travel through the internet to remote servers before results return to the user. Thinkputer runs supported AI workloads on a Local Private Server (LPS), bringing AI computing closer to your users and data.
Local processing can reduce network delay and provide direct access to dedicated AI hardware, helping suitable business workloads respond faster and more consistently.
Cloud AI vs Fast Local AI
| Performance | Cloud AI | Thinkputer Local AI |
|---|---|---|
| Network Distance | Remote Data Centre | Local Network |
| Internet Latency | Can Affect Response | Avoided for Local Processing |
| Computing Resources | Shared / Provider Managed | Dedicated Local Hardware |
| Response Consistency | Internet / Provider Dependent | Locally Controlled |
Why Can Local AI Be Faster?
Self-Hosted AI processes suitable requests directly on your own server instead of sending every task across the internet to an external provider.
Actual speed depends on the AI model, GPU, workload and number of simultaneous users, but Thinkputer gives your organization dedicated computing resources for supported local AI.
Frequently Asked Questions
Not always. Performance depends on the model, hardware and task. Thinkputer can be faster for suitable workloads because local processing avoids internet latency and uses dedicated local computing resources.
AI model size, GPU performance, available memory, workflow complexity and simultaneous users can all affect speed. Higher-capacity Thinkputer models are designed for heavier workloads.
Bring AI Computing Closer
Move suitable workloads to a Thinkputer Local AI Server for faster local access and dedicated AI computing.
See the Difference
Local AI Can Make
Complete Invoice AI Processing*
Measured on our invoice extraction and formatting workflow. Performance varies by model, workload, configuration, authentication, internet service, device and service conditions.
| Thinkputer 10 | 9 seconds |
| DeepSeek Cloud | 73 seconds |
| ChatGPT Cloud | 84 seconds |