Thinkputer AI: Token Expiry -> Unlimited Usage
Submitted by on Thu, 08/27/2026 - 20:30Thinkputer AI: Token Expiry → Unlimited Usage
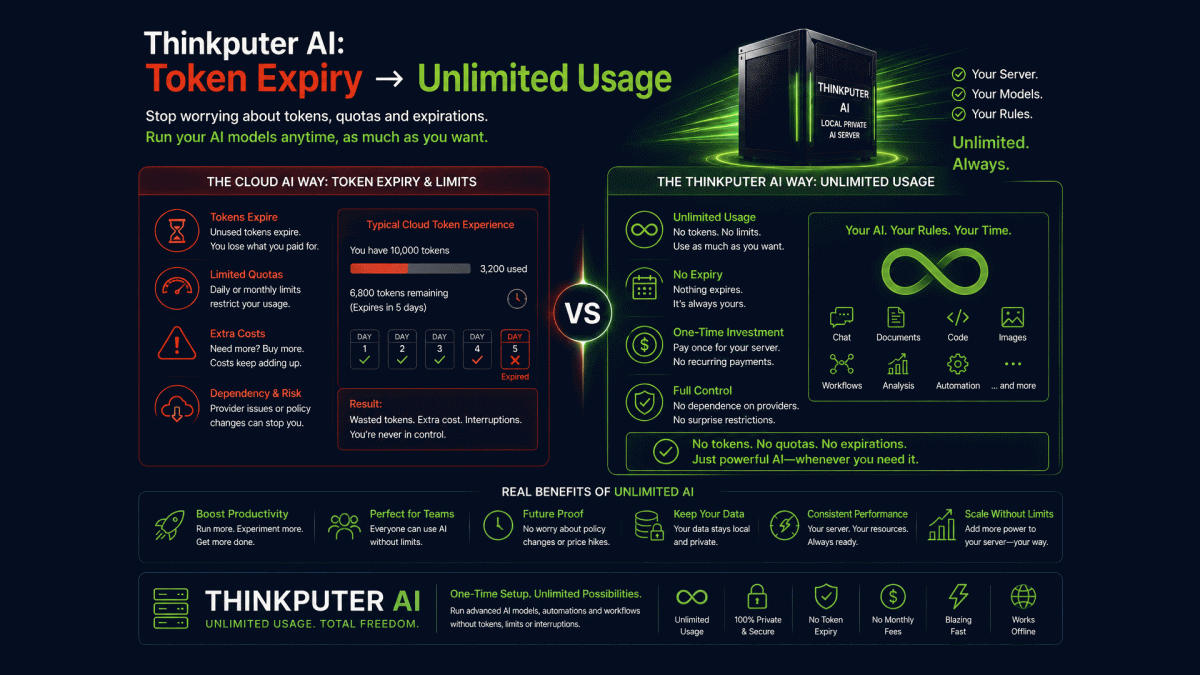
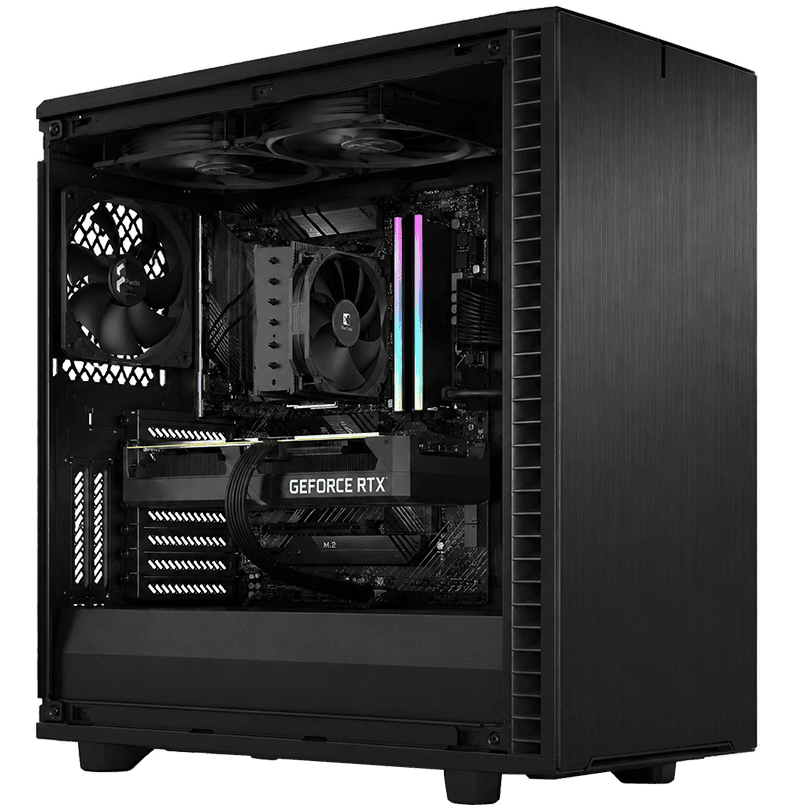
Cloud AI services may use API tokens, usage limits, quotas or credentials that can expire or require renewal. Thinkputer runs supported AI models locally on a Local Private Server (LPS), removing those cloud token limitations from local AI processing.
Your organization can use supported local AI repeatedly without purchasing additional API tokens or waiting for usage limits to reset. The practical limit becomes your own server's computing capacity rather than a provider's token allowance.
Cloud Tokens vs Thinkputer Local AI
| Usage | Cloud AI | Thinkputer Local AI |
|---|---|---|
| API Token Expiry | May Expire / Require Renewal | Not Required for Local AI |
| Usage Quotas | Plan Dependent | No Provider Quota |
| Per-Token Charges | Often Usage Based | $0 for Supported Local Processing |
| Continuous Use | Provider Limits May Apply | Use Your Available Local Computing Power |
Use AI When Your Business Needs It
With Self-Hosted AI, supported local workloads are not controlled by an external provider's token balance, API quota or account expiration.
Unlimited usage means there is no Thinkputer-imposed token quota for supported local AI. Actual throughput still depends on your hardware, model size, number of users and workload.
Frequently Asked Questions
Supported AI models running locally do not require paid cloud API tokens. External cloud AI services can still require their own API keys, tokens, subscriptions and usage limits.
There is no Thinkputer-imposed token quota for supported local AI processing. Usage is instead limited by the available computing resources, storage, workload and capacity of your Thinkputer server.
Move Beyond Token Limits
Use your own Thinkputer Local AI Server for suitable workloads and keep cloud AI available only when you choose to use it.
See the Difference
Local AI Can Make
Complete Invoice AI Processing*
Measured on our invoice extraction and formatting workflow. Performance varies by model, workload, configuration, authentication, internet service, device and service conditions.
| Thinkputer 10 | 9 seconds |
| DeepSeek Cloud | 73 seconds |
| ChatGPT Cloud | 84 seconds |